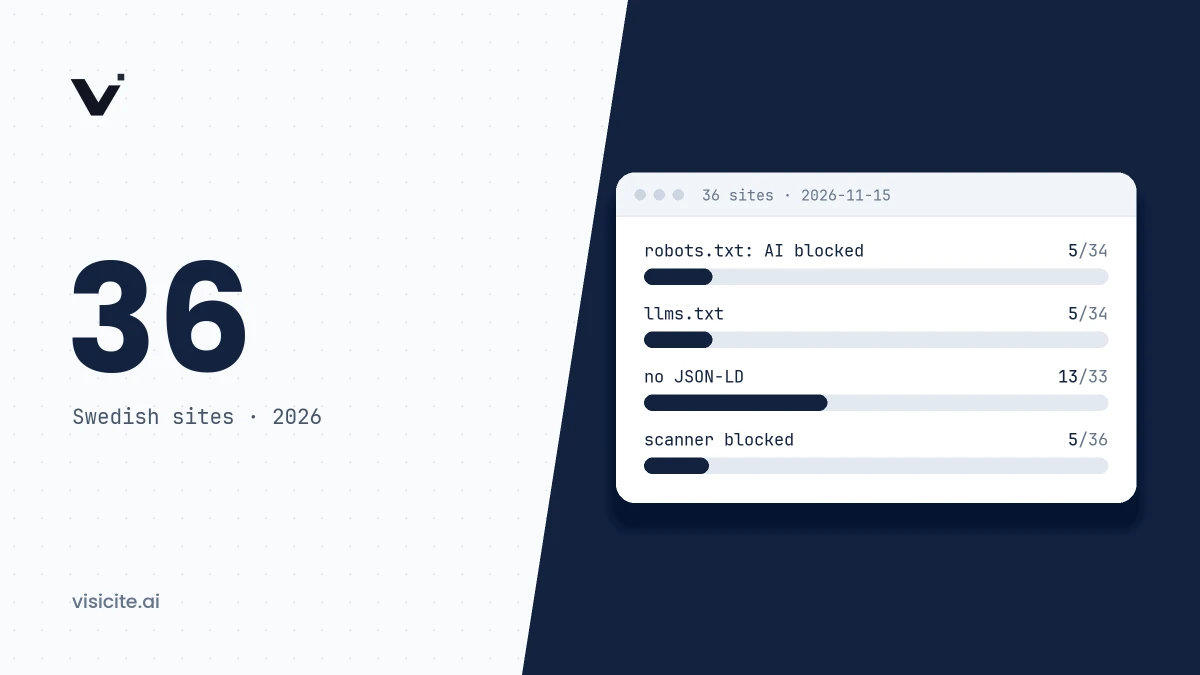

We examined the start page of 36 large Swedish websites on 15 November 2026. No site outside the news media blocks AI crawlers in robots.txt, but 26 of 34 do not mention them at all. Five of 34 have an llms.txt, and 13 of 33 start pages carry no structured data. Five sites did not let our scanner in at all. Here are the full results, how we measured, and what the numbers do not tell you.
In brief
- Only the news media have taken a position. All five news sites block at least one AI crawler in robots.txt. None of the other 29 sites whose robots.txt could be read blocks any.
- Most have made no choice. 26 of 34 sites do not name a single AI crawler in robots.txt. They are open, but apparently not by an explicit decision.
- llms.txt is rare. Five of 34 sites have a working llms.txt. Two answer the address with an ordinary HTML page.
- Structured data is often missing. 13 of 33 start pages have no JSON-LD in their HTML. Of the five government agencies, only one has it.
- Bot protection stops more than robots.txt does. Five of 36 sites answered our scanner with a block page instead of the start page, even where their robots.txt welcomes automated visitors.
What we examined
The sample is 36 well-known Swedish websites in eight sectors: news media, retail, banking and insurance, telecom and energy, government agencies, travel and transport, industry, and marketplaces. It is not a random sample and not a ranking of Sweden's most visited sites. It is a cross-section of large organisations that most Swedes know.
For each site we did two things on 15 November 2026:
- Visicite's free scan of the start page. This is the same scan anyone can run on the free scan page: rule-based checks of technical access, structured data, content structure and publisher identity, combined into a score from 0 to 100.
- An independent check. We fetched each site's robots.txt, llms.txt and start page HTML directly and interpreted robots.txt with a parser that follows the standard, RFC 9309. Every statement about robots.txt, llms.txt and JSON-LD in this article comes from that check, not from the score.
The second check earned its place. It exposed five bugs in our own scanner, among them that it rejected structured data written in @graph form and accepted an HTML error page as an llms.txt. The bugs are fixed and every site was scanned again before the results were compiled.
AI crawlers in robots.txt: the media versus everyone else
AI companies use different crawlers for different purposes. GPTBot, ClaudeBot and Google-Extended concern model training. OAI-SearchBot, Claude-SearchBot and PerplexityBot build the search indexes that ChatGPT, Claude and Perplexity retrieve sources from. The difference is explained in the guide to robots.txt for AI crawlers.
Robots.txt could be read for 34 of the 36 sites. Two, ica.se and hm.com, answered our request with a 403 error.
| Position in robots.txt | Sites | Which |
|---|---|---|
| Names no AI crawler | 26 | Every agency, bank and telecom operator in the sample, and most retailers |
| Names AI crawlers without shutting any out of the site | 3 | apotea.se, elgiganten.se, volvocars.com |
| Blocks training, allows AI search | 1 | svt.se |
| Blocks training and part of AI search | 2 | aftonbladet.se, svd.se |
| Blocks both training and AI search | 2 | dn.se, expressen.se |
The five news sites have chosen three different lines:
- dn.se and expressen.se shut out both the training crawlers and the search crawlers of OpenAI, Anthropic and Perplexity, and also the agents that fetch a page when a user asks for it (ChatGPT-User, Claude-User, Perplexity-User).
- aftonbladet.se and svd.se block ClaudeBot, Claude-SearchBot, PerplexityBot, Google-Extended and CCBot, but neither GPTBot nor OAI-SearchBot.
- svt.se, the public service broadcaster, blocks training crawlers such as GPTBot, ClaudeBot and Google-Extended but explicitly admits the three search crawlers.
No site in the sample blocks Googlebot or bingbot. That matters, because the AI answers in Google Search are built on Googlebot's index. According to Google's documentation, blocking Google-Extended does not affect Google Search.
svt.se and apotea.se also use lines beginning with Content-Signal, a proposed addition to robots.txt, to state how their content may be used. SVT writes ai-train=no, search=yes, ai-input=yes for the search crawlers. Apotea, an online pharmacy, writes search=yes, ai-input=yes, ai-train=yes. They are the two clearest examples in the sample of a stated choice, in opposite directions.
For the 26 sites that do not mention AI crawlers, the default applies: whatever is not disallowed is allowed. The outcome is openness, but we cannot see whether it is intended. That matters on the day someone in the organisation asks whether its content is used to train AI models, because the answer is yes for as long as nobody has said no.
llms.txt: five of 34
A working llms.txt, meaning a Markdown text file at /llms.txt, exists on five sites: apotea.se, coop.se, elgiganten.se, klarna.com and tele2.se. That is 15 percent of the 34 sites where the address could be checked.
Two sites, postnord.se and sj.se, answer the address with status code 200 but send an ordinary HTML page. To a person it looks like a page that does not exist. To a program it looks as if the file is there. It is a common mistake and a good reason to make missing addresses return 404.
How much the file matters is an open question. It is a proposal, not a standard, and Google states in its documentation on AI features that no special AI files are needed to appear there. The background is in the guide to llms.txt.
Structured data: one start page in three has no JSON-LD
The start page HTML could be fetched for 33 sites. Of these, 20 have some form of JSON-LD and 13 have none: arbetsformedlingen.se, clasohlson.com, coop.se, forsakringskassan.se, klarna.com, nordea.se, polisen.se, seb.se, sj.se, skatteverket.se, svt.se, systembolaget.se and tele2.se.
18 of the 33 describe themselves with an organisation type such as Organization, NewsMediaOrganization or OnlineStore. That is the statement that makes it unambiguous who is behind the site.
Two caveats. We read the HTML the server sends, so structured data added afterwards by JavaScript is not counted. And the start page is not the whole site: a site can have excellent structured data on product and article pages without having any on its start page. Structured data is not a requirement for appearing in AI answers either, but it makes facts unambiguous. More in the guide to JSON-LD and structured data.
Headings and JavaScript
Five of 33 start pages have no H1 heading in the HTML from the server: aftonbladet.se, coop.se, expressen.se, svd.se and telenor.se. On coop.se and telenor.se the heading appears only after JavaScript has run. Eight sites have more than one H1, and svt.se has 60, because every news headline on its start page is marked up as an H1.
Four of the 31 sites the scanner could analyse depend heavily on JavaScript to show their content: coop.se, ica.se, sj.se and telenor.se. Google renders JavaScript. For the other AI services' crawlers it is not documented that they do, which we cover in the article on technical factors for AI visibility. Content that exists only after rendering may therefore be invisible to them.
Five sites stopped the scanner
Five of 36 sites did not answer with their start page when our scanner requested it:
| Site | Response to the scanner | Ordinary browser-style request from the same computer |
|---|---|---|
| hm.com | 403, "Access Denied" | 403 |
| volvocars.com | 403, "Access Denied" | 403 |
| elgiganten.se | 429, security checkpoint | 200 |
| dn.se | 406 | 200 |
| expressen.se | 406 | 200 |
This says nothing about how these sites treat the crawlers of OpenAI, Anthropic or Google. Our scanner is not one of them, and bot protection often lets through known crawlers that can be verified by their IP addresses. The responses also varied: in an earlier run the same day, the scanner did receive the start pages of dn.se and expressen.se.
The pattern is still worth knowing about, for two reasons. The first is that bot protection sits in front of robots.txt. volvocars.com names some twenty AI crawlers in its robots.txt and shuts them out of only parts of the site, and elgiganten.se has both an llms.txt and its own rules for the AI services' user-triggered fetchers. Even so, our automated request was stopped at both by a barrier that appears in neither file. Robots.txt describes what a site wants to allow. The firewall decides what actually happens.
The second is that the person responsible for the content is rarely the person who configures the bot protection. If you want to know whether AI crawlers actually reach your site, reading robots.txt is not enough. You need to look in the server logs for their user agents and see which status code they received.
The five sites have no score in the table below, because the scanner analysed a block page and not their content.
Scores by site and sector
For the 31 sites that could be analysed, the mean score was 79 and the median 78, with 52 as the lowest and 96 as the highest value.
| Sector | Sites | Mean score |
|---|---|---|
| Industry and automotive | 1 | 90 |
| Telecom and energy | 4 | 86 |
| Marketplaces | 2 | 84 |
| Travel and transport | 3 | 79 |
| Retail | 6 | 78 |
| Media | 3 | 77 |
| Public sector | 5 | 76 |
| Banking and insurance | 7 | 75 |
Read the sector figures with care. The groups are small, from one to seven sites, and the differences between them are smaller than the spread within them.
The full results, sorted by score:
| Site | Sector | Score | AI crawlers in robots.txt | llms.txt | JSON-LD on start page |
|---|---|---|---|---|---|
| vattenfall.se | Telecom and energy | 96 | No AI crawlers blocked | No | Organization |
| hemnet.se | Marketplaces | 93 | No AI crawlers blocked | No | Organization |
| handelsbanken.se | Banking and insurance | 91 | No AI crawlers blocked | No | FAQPage |
| scania.com | Industry and automotive | 90 | No AI crawlers blocked | No | Organization |
| telia.se | Telecom and energy | 90 | No AI crawlers blocked | No | Organization |
| 1177.se | Public sector | 86 | No AI crawlers blocked | No | Organization, WebPage |
| postnord.se | Travel and transport | 86 | No AI crawlers blocked | No | Organization |
| telenor.se | Telecom and energy | 86 | No AI crawlers blocked | No | Organization |
| folksam.se | Banking and insurance | 85 | No AI crawlers blocked | No | Organization |
| ikea.com | Retail | 85 | No AI crawlers blocked | No | FurnitureStore, OnlineStore, WebSite |
| apotea.se | Retail | 84 | No AI crawlers blocked | Yes | OnlineStore, WebSite |
| ica.se | Retail | 84 | Could not be read | – | – |
| lansforsakringar.se | Banking and insurance | 82 | No AI crawlers blocked | No | Organization, WebPage, WebSite |
| sas.se | Travel and transport | 82 | No AI crawlers blocked | No | Airline, WebSite |
| svd.se | Media | 82 | Blocks training plus Claude-SearchBot and PerplexityBot | No | NewsMediaOrganization |
| aftonbladet.se | Media | 78 | Blocks training plus Claude-SearchBot and PerplexityBot | No | NewsMediaOrganization, WebPage |
| nordea.se | Banking and insurance | 76 | No AI crawlers blocked | No | None |
| arbetsformedlingen.se | Public sector | 75 | No AI crawlers blocked | No | None |
| polisen.se | Public sector | 75 | No AI crawlers blocked | No | None |
| blocket.se | Marketplaces | 74 | No AI crawlers blocked | No | Organization |
| forsakringskassan.se | Public sector | 74 | No AI crawlers blocked | No | None |
| swedbank.se | Banking and insurance | 74 | No AI crawlers blocked | No | BreadcrumbList |
| systembolaget.se | Retail | 74 | No AI crawlers blocked | No | None |
| coop.se | Retail | 73 | No AI crawlers blocked | Yes | None |
| skatteverket.se | Public sector | 72 | No AI crawlers blocked | No | None |
| svt.se | Media | 71 | Blocks training, allows AI search | No | None |
| sj.se | Travel and transport | 70 | No AI crawlers blocked | No | None |
| tele2.se | Telecom and energy | 70 | No AI crawlers blocked | Yes | None |
| seb.se | Banking and insurance | 68 | No AI crawlers blocked | No | None |
| clasohlson.com | Retail | 67 | No AI crawlers blocked | No | None |
| klarna.com | Banking and insurance | 52 | No AI crawlers blocked | Yes | None |
| dn.se | Media | Blocked | Blocks training and AI search | No | NewsMediaOrganization |
| elgiganten.se | Retail | Blocked | No AI crawlers blocked | Yes | OnlineStore, WebSite |
| expressen.se | Media | Blocked | Blocks training and AI search | No | NewsMediaOrganization, WebPage |
| hm.com | Retail | Blocked | Could not be read | – | – |
| volvocars.com | Industry and automotive | Blocked | No AI crawlers blocked | No | – |
The AI crawler column is based on our reading of robots.txt for the start page. "Training" refers to GPTBot, ClaudeBot, Google-Extended, Applebot-Extended, CCBot and Bytespider, and "AI search" to OAI-SearchBot, Claude-SearchBot and PerplexityBot. The JSON-LD column shows the main types in the HTML from the server. A dash means the information could not be fetched.
What the score does not tell you
- It measures prerequisites, not outcomes. The score shows how well a page meets known and reasonable technical prerequisites. It does not show whether the site is cited in AI answers. A large bank or government agency is cited because of what it is, whatever its H1 headings look like.
- It covers one page. We analysed the start page, which is often an entry point with little text. Inner pages can look entirely different.
- It is not fully comparable between sites. The scanner runs a different number of checks depending on what type of page it judges it is looking at, between 24 and 36 in this sample. Two sites with the same score have not necessarily been assessed on exactly the same points.
- It is a snapshot. Everything was measured on 15 November 2026. A robots.txt can change in a minute.
- Blocking can be the right decision. A media company that shuts out training crawlers scores lower on that check with us, but is making a business decision about its content. The score values openness, not business strategy.
Three things to take away
- Make an explicit choice about AI crawlers. 26 of 34 large Swedish sites have not. Decide whether you want to contribute to training and whether you want to appear in AI search, and write it into robots.txt. They are two different decisions and they are controlled separately.
- Check what actually happens, not only what the files say. Bot protection in a CDN or firewall can stop visitors that robots.txt welcomes. The server logs show the truth.
- Say who you are on the start page. A third of the start pages have no structured data. An Organization markup with name, logo and links to your official profiles is a small effort.
To see how your own start page does against the same checks, run the free scan. The background to the checks is in the guide to generative engine optimization.
Questions about the study
How were the sites selected?
We chose well-known Swedish websites with large audiences in eight sectors. The sample is not random and does not claim to be the 36 largest sites in Sweden. Four sites were added afterwards to compensate for those that stopped the scanner.
Do Swedish websites block ChatGPT?
In our sample, only the news media do. dn.se, expressen.se and svt.se block OpenAI's training crawler GPTBot. dn.se and expressen.se also block the search crawler OAI-SearchBot, which according to OpenAI's documentation means their pages are not shown in ChatGPT's search answers. No bank, government agency, retailer or telecom operator in the sample blocks either of them in robots.txt.
Can I get the full dataset?
The table above contains the main facts for each site. You can repeat the analysis yourself by running the free scan on any of the start pages and reading the site's robots.txt and llms.txt directly in a browser.
Will the study be repeated?
The measurement is built so that it can be run again with the same list and the same checks. This article describes the situation on 15 November 2026.